Overview
This import updates existing post content in NeuronCx using data from a Google Sheet. For each row, it pulls in the transaction attribute details — properties, relations, and text — and applies them to the matching post content record. You can also choose whether to re-index the content after the update. Use this import when you need to refresh post content with the latest attribute data in bulk, without updating each record manually.This import updates existing post content only. Every row must include all mandatory columns — rows missing any of them will not be processed.
Prerequisites
- Your Google Sheet must be shared with edit access so NeuronCx can read from it.
- All mandatory columns must be present and filled in for every row — see the column reference below.
- Any additional columns you include must match a Standard Schema key that has already been onboarded for your institution. You can check which keys are available at Content Settings > Standard Schema.
- The post content records, transaction attributes, and post sections you’re referencing must already exist in NeuronCx.
Preparing Your Sheet
Your sheet must include all of the following mandatory columns. Additional standard schema columns are optional.Mandatory columns
Optional columns
In addition to the mandatory columns, you can include extra columns to update standard schema fields. The column header must exactly match the Standard Label of the schema key as it appears in your institution’s Standard Schema settings.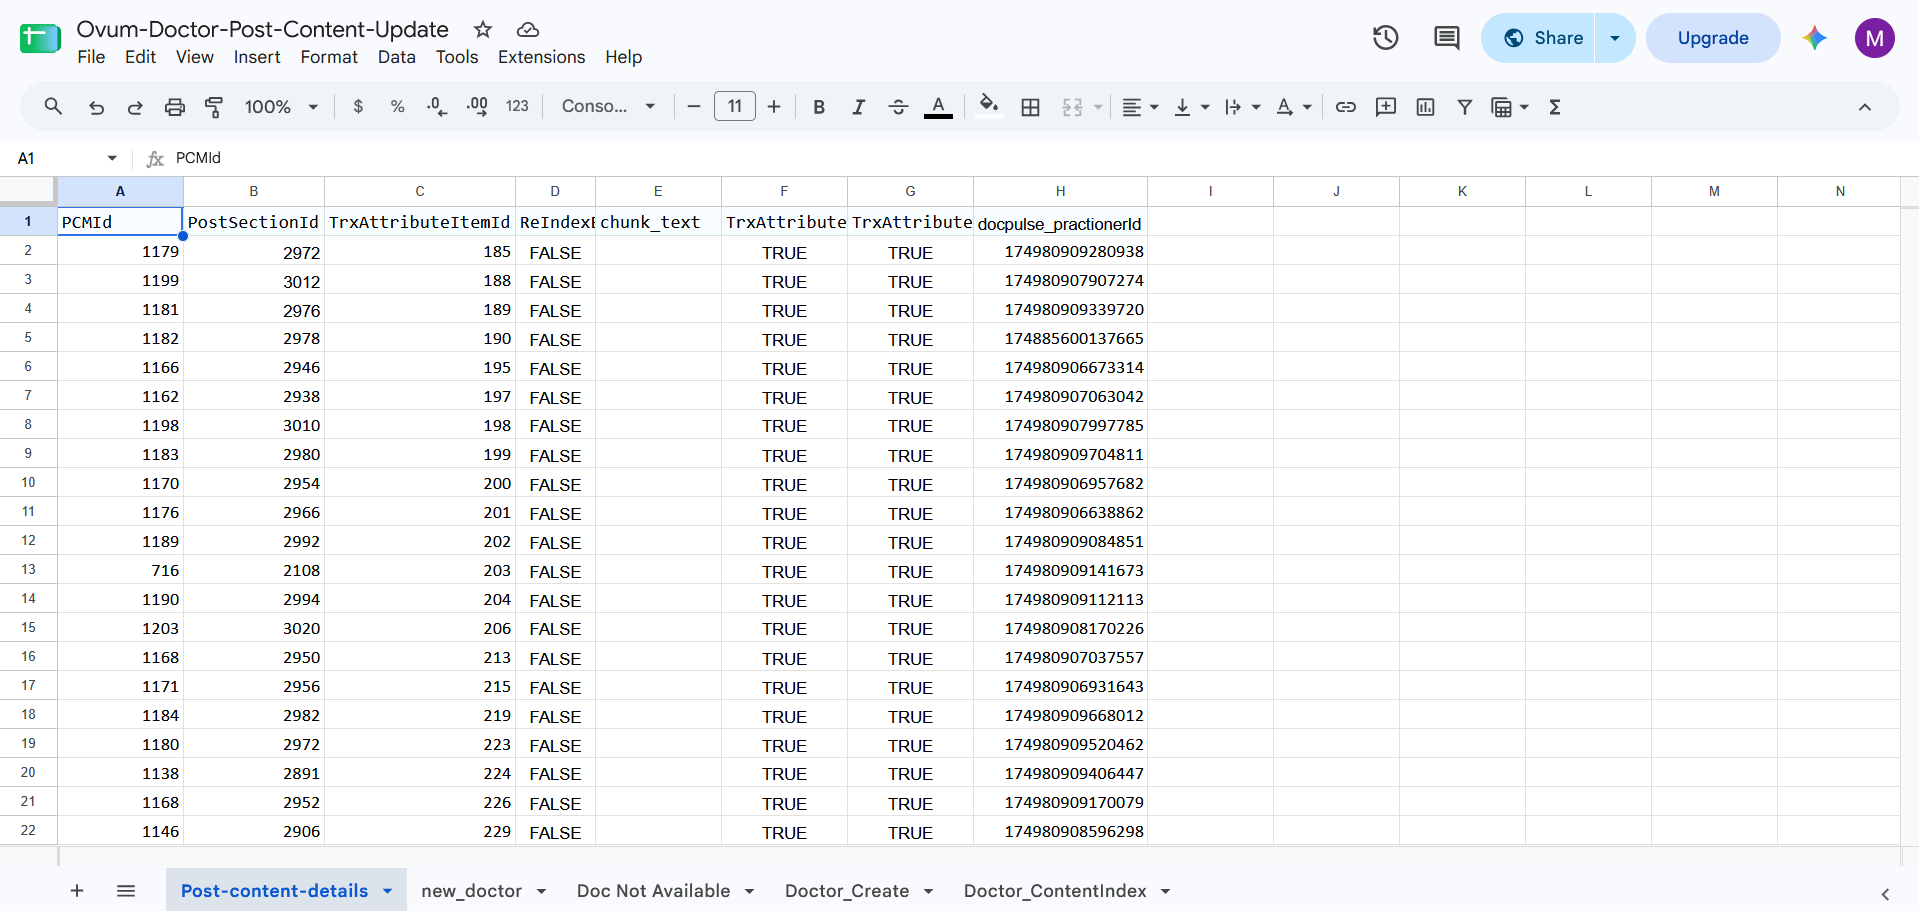
Running the Import
Setting up a new import
1
Open Imports
Navigate to Home > Ontology > Attribute Settings & Bulk Edit, then click the Imports tab.
2
Click + Import
Click the + Import button in the top right to open the New Import modal.
3
Give it a label
Enter a name that describes this import — for example, “Doctor Post Content Attribute Update.”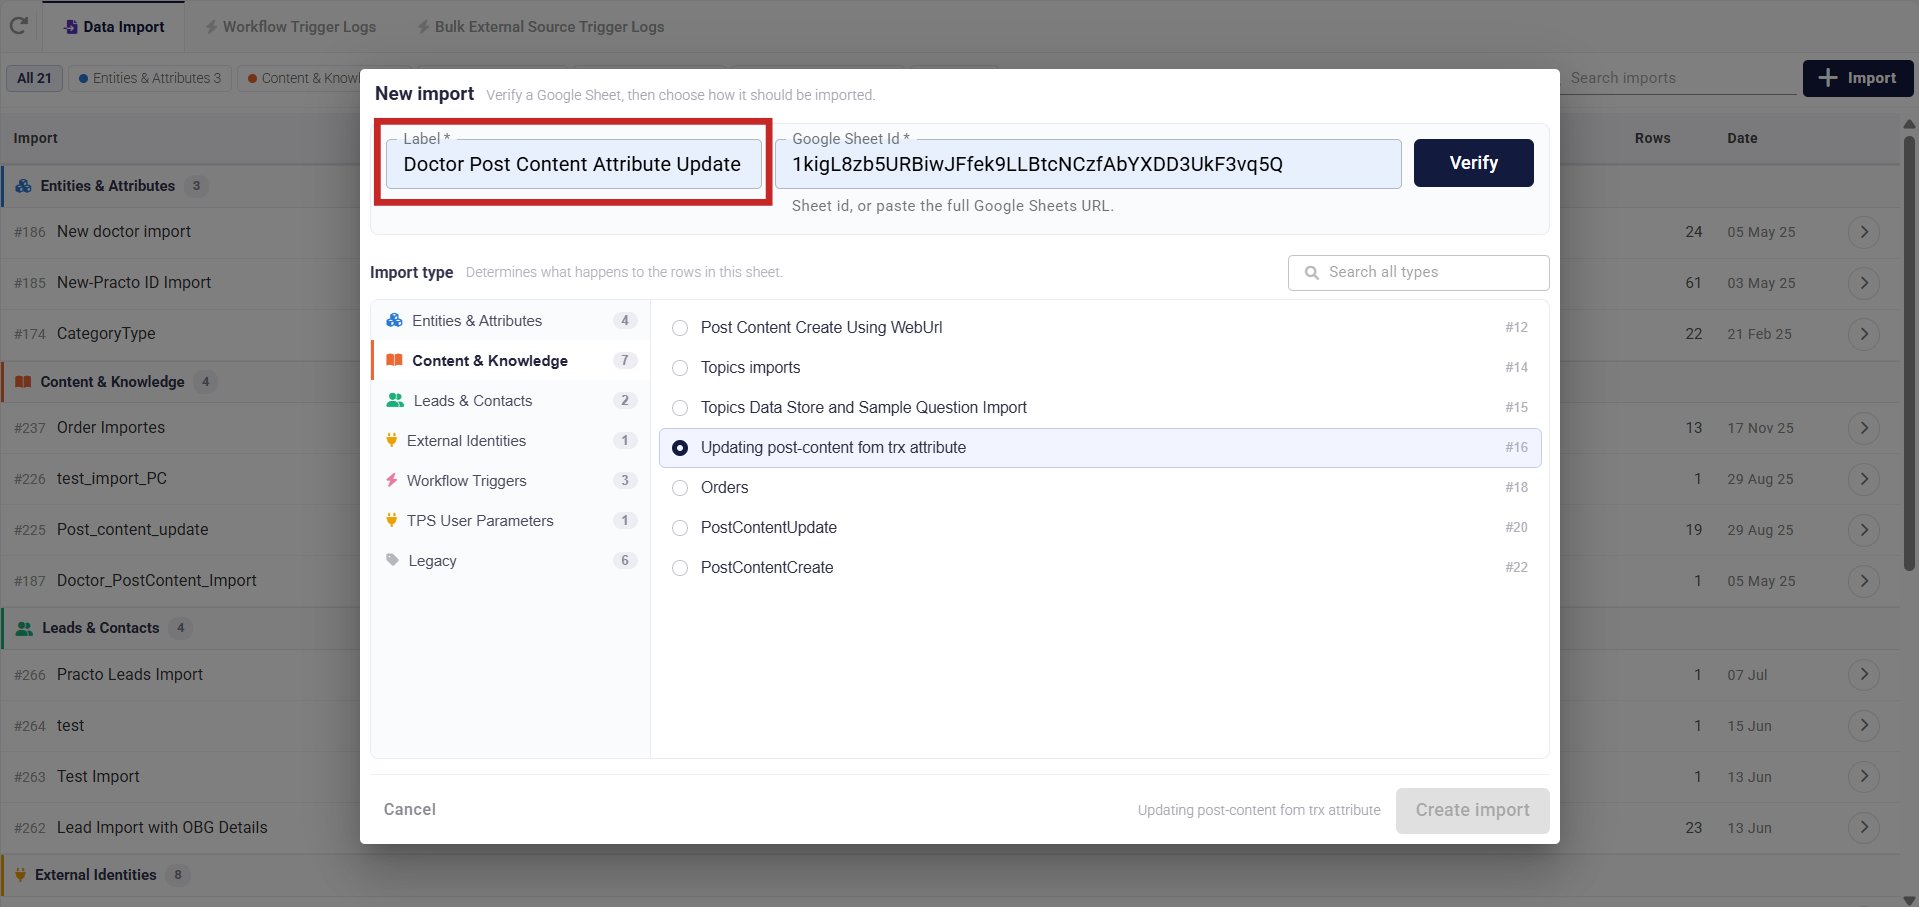
4
Add the Google Sheet ID
Paste the sheet ID or the full Google Sheets URL — NeuronCx will extract the ID automatically.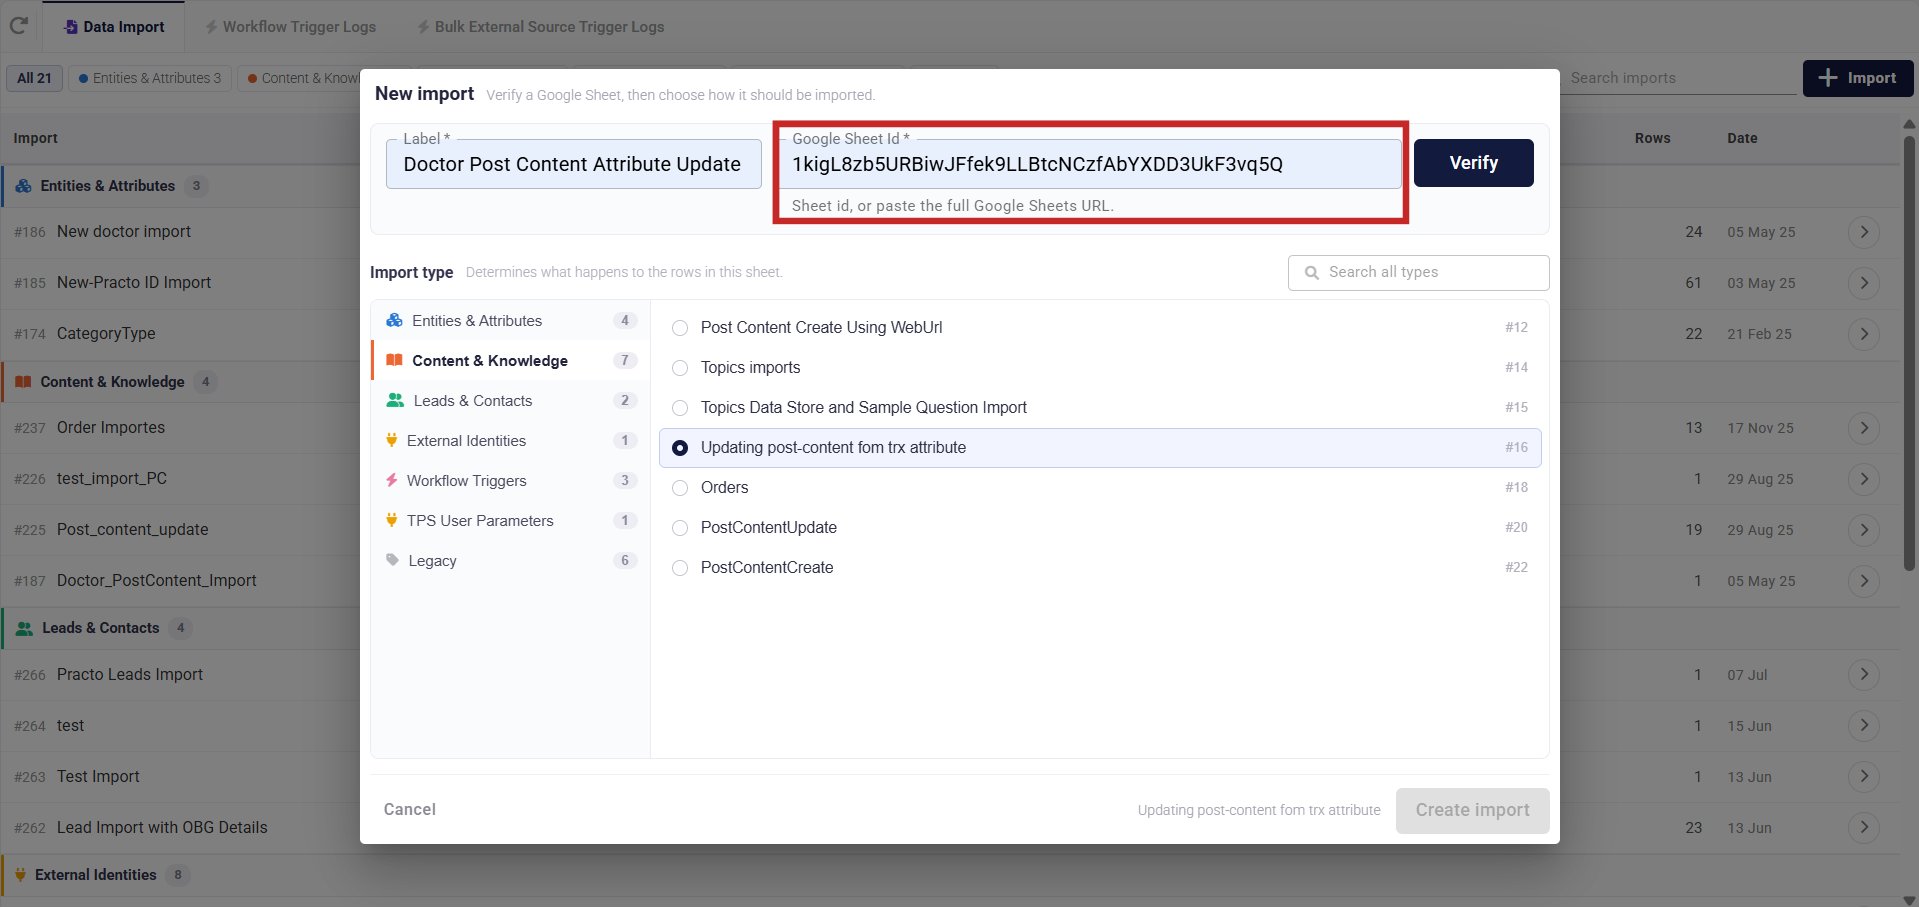
5
Verify
Click Verify. NeuronCx confirms it can read the sheet and shows you the row and column count — use this to catch an empty or wrong sheet before continuing.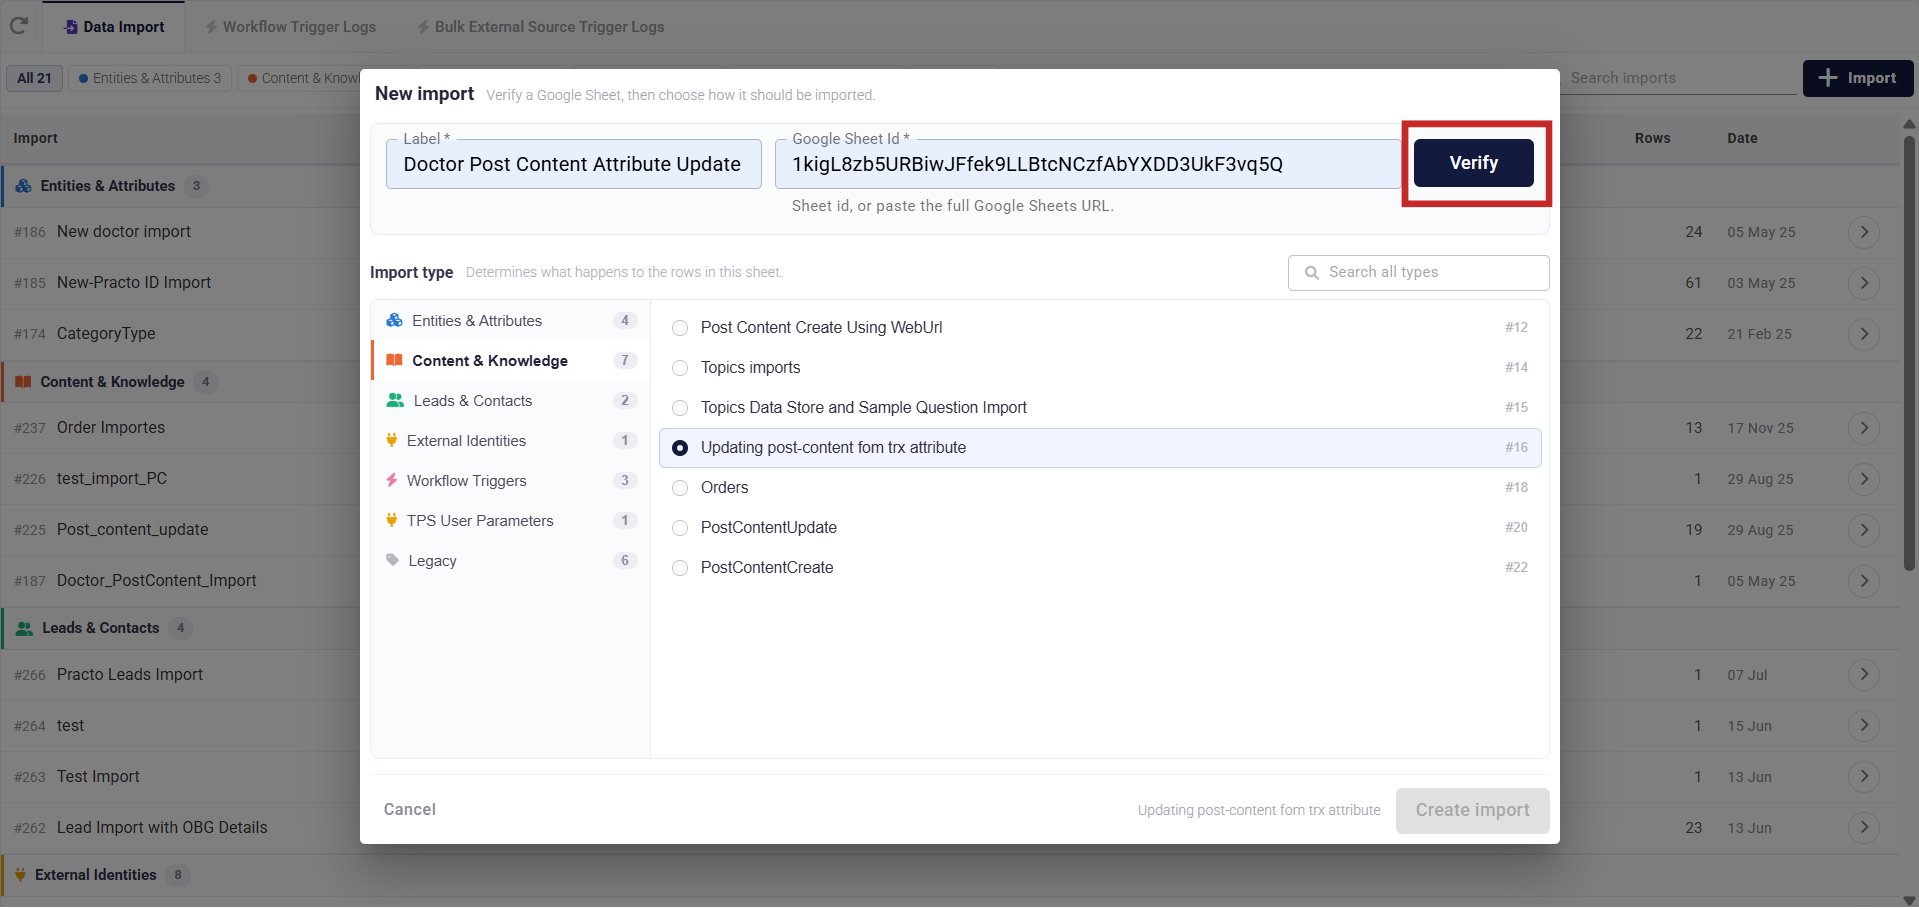
6
Select the import type
In the Import type panel on the left, select Content & Knowledge. Then choose Updating post-content from trx attribute (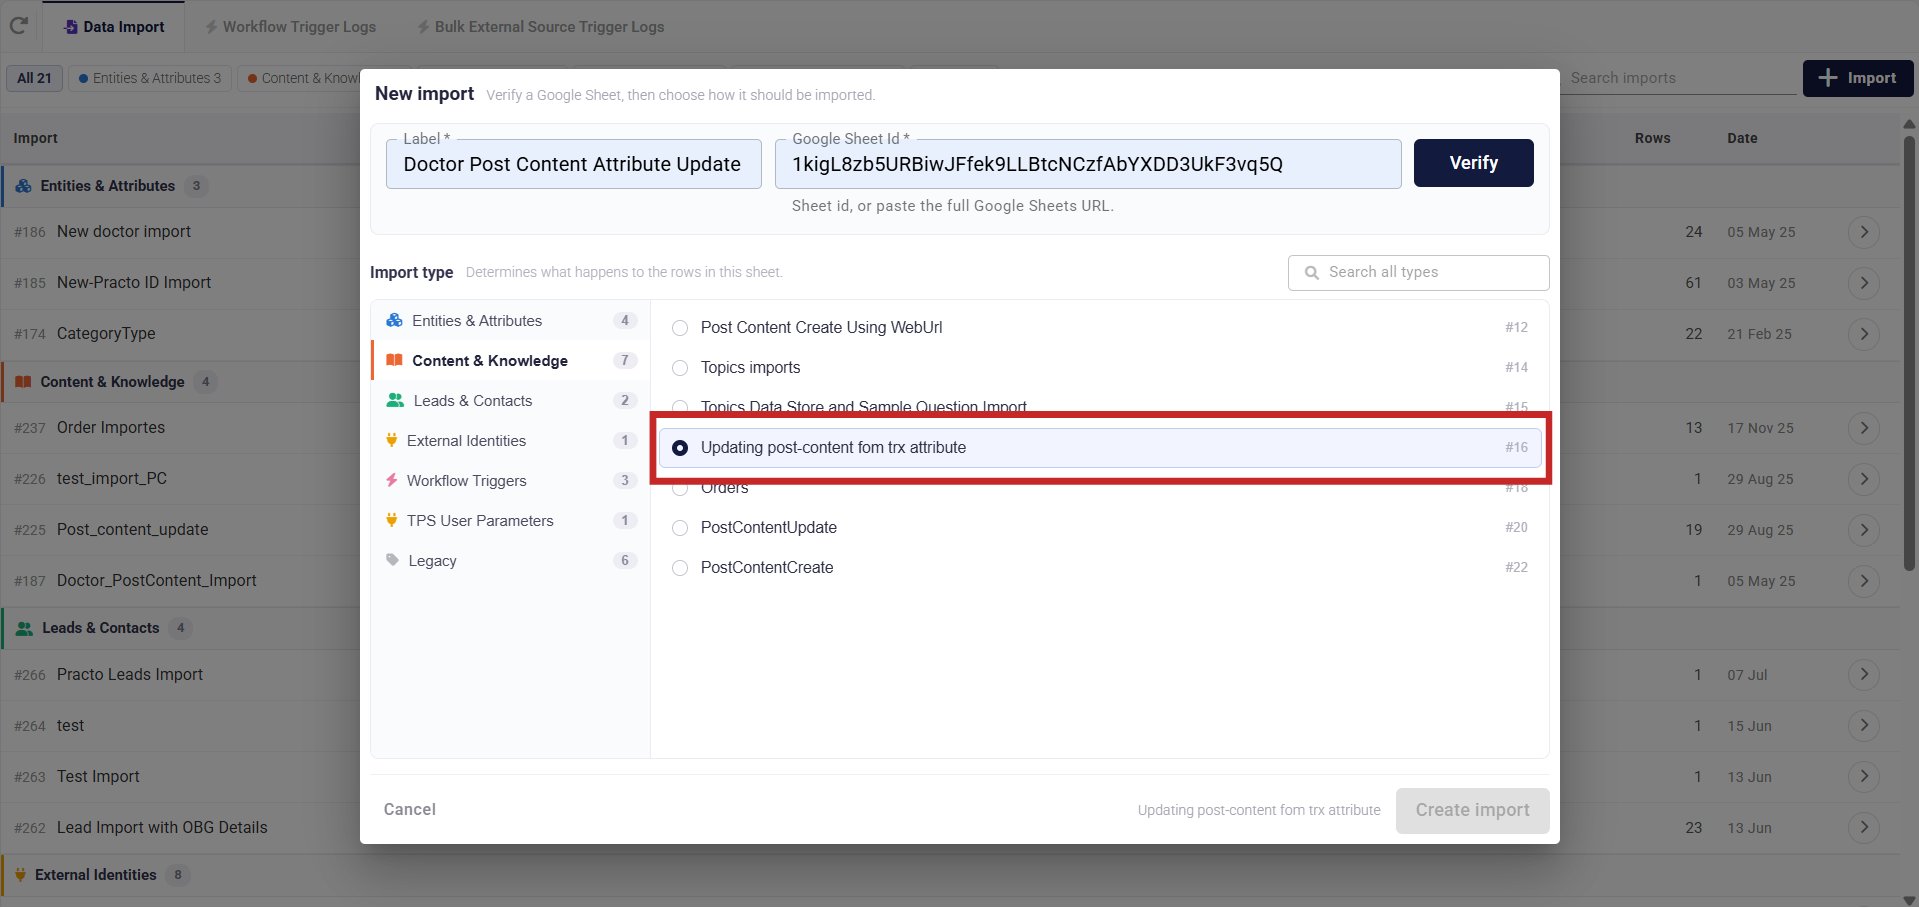
#16) from the list on the right.7
Create the import
Click Create import. The import now appears in your list under Content & Knowledge, ready to run.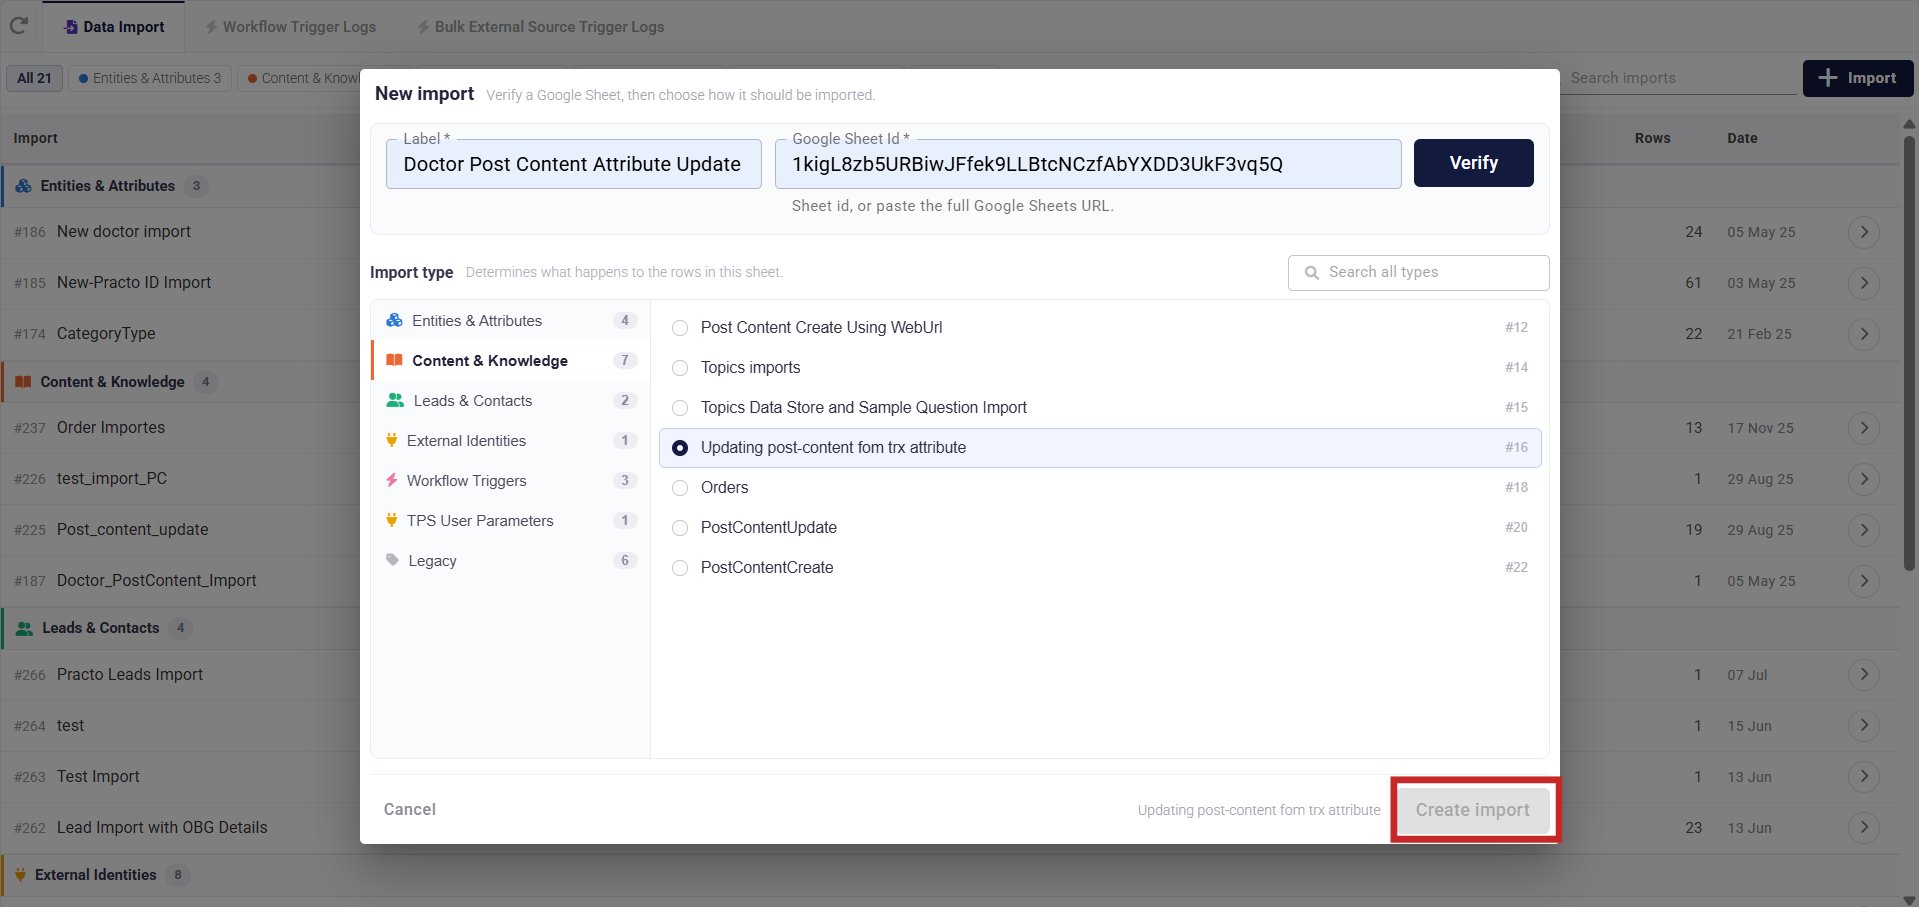
Running the import
1
Find the import
From the Data Import list, locate the import you just created. You can filter by Content & Knowledge to narrow the list.
2
Open the import
Click the arrow icon on the import row to open it.
3
Click Import
Click Import to run it.
Checking the Result
Once the run completes, the history table shows how many rows were read and how many records were updated. Click a run’s Status to open a detailed breakdown showing which rows succeeded, failed, or were skipped.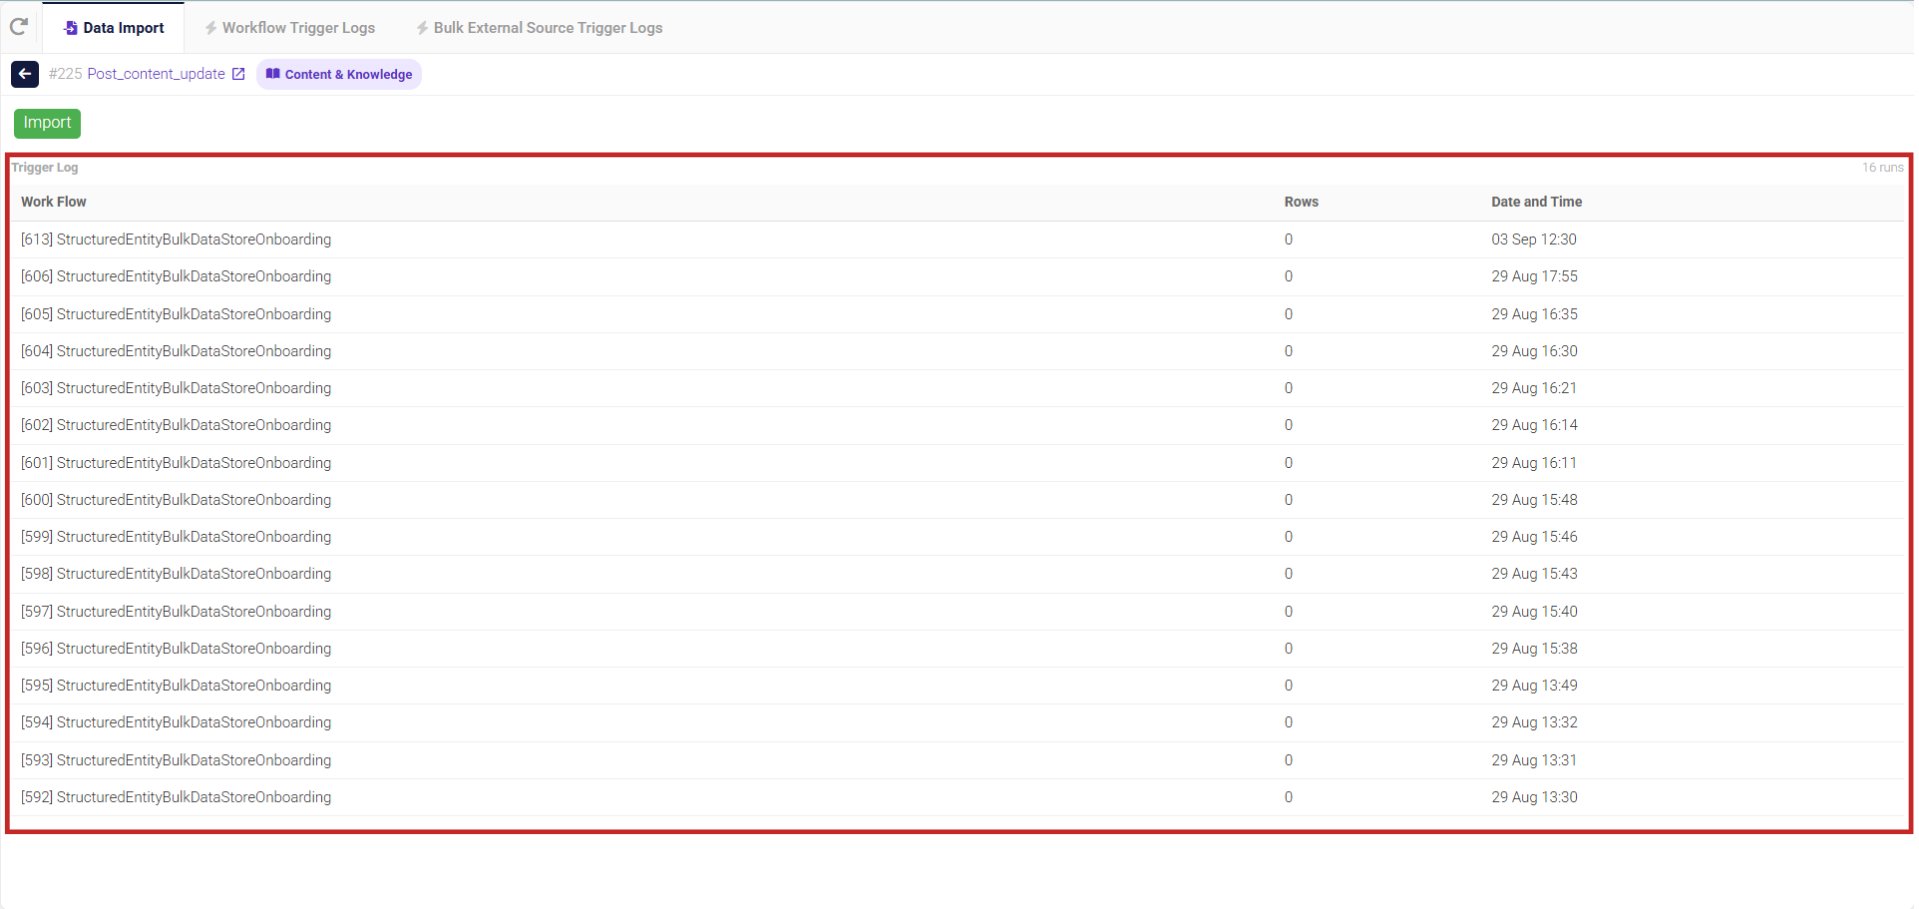
Limits to Keep in Mind
- All seven mandatory columns must be present and filled in for every row — a row missing any of them will not be processed.
ReIndexEnabled,TrxAttributePropertiesEnabled, andTrxAttributeRelationsEnabledonly acceptTrueorFalse. Any other value may cause that row to be skipped.- Optional columns must exactly match a Standard Label from your institution’s Standard Schema — unrecognised column headers are ignored.
- This import updates existing post content only. It does not create new post content records.
- Only one import runs at a time. If another import is already running, this one will queue and wait its turn.